Deployment files
A deployment file is the saved form of a deployment: a file you can commit to source control, attach to a task, or hand to an operator to re-run later. The Deployment tab's toolbar is the primary place you create, save, open, and run them.
Saving a deployment
Three save options live on the Deployment tab's toolbar:
- Save (Ctrl+S). Save to the deployment's current path. First-time saves open a file dialog so you can pick a location.
- Save As (Ctrl+Shift+S). Save to a different path.
- Export to Task. Attach the deployment file to a task in your task tracker (Jira or Azure Boards). You are prompted for a task ID each time and can look it up with Find to confirm it exists before exporting, so you can attach to any task, not just the one associated with the current branch. Only available when you're connected to a task tracker.
The default on-disk location and folder pattern for saved deployments are configured on the workspace's Settings → Release tab. That tab also controls whether deployments produced by the Release Workflow are stored as workspace files, attached to a task, or both.
Opening an existing deployment
From the Deployment tab toolbar:
- Open (Ctrl+O). Pick an existing deployment file.
From the main menu you also have:
- Deployment → Open File…. Same as the toolbar Open.
- Deployment → Recent Files. Pick from the recent list.
- Deployment → Import from Task…. Load a deployment attached to a task. You're prompted for a task ID each time, so you can import from any task.
- Deployment → Deploy from Manifest…. Load a deployment file and deploy it immediately.
Running a deployment
Click Deploy (Ctrl+Shift+E) on the Deployment toolbar. This opens the Run Script dialog (the same dialog as the single-component Run) with a Mode picker for COMMIT vs ROLLBACK.
Pick the mode, click Run. DataStar executes every component in order; when it finishes a log tab opens showing the per-component results.
Previewing before you run
Several toolbar actions run against the deployment without actually deploying:
-
What If. Preview of what the deployment would do.
-
Database Snapshot. Compare the deployment's items against the current database state. You're prompted for the database to compare against, and each row's status shows
MATCH,CHANGED,NEW,REMOVE(a delete document whose component the database holds),N/A(cannot be compared) or, for a changeset,CONFLICT: the database no longer holds rows the changeset changed, so deploying would stop. A changeset is compared row by row against what the database holds now.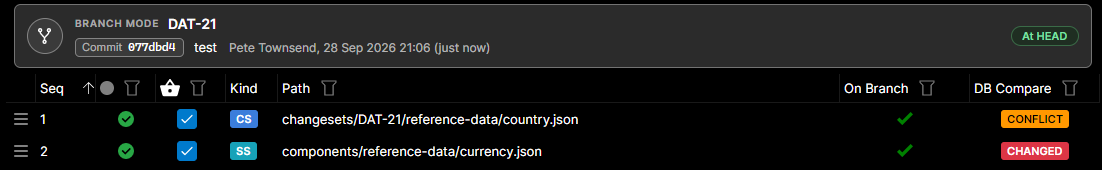
Hover over a status to see why: an
N/Aitem names what stopped it being compared, and a full document of a changeset-deploying component carries the warning that deploying it replaces other work items' rows.To see what lies behind a row's status, right-click it and use Compare With… → Compare with DB Snapshot (see Per-row preview).
-
SQL Export. Write the deployment out as a SQL script for review.
-
Export Reversal Script. Generate a rollback script for the deployment against a database you choose - no deployment or audit tables required. See Reversal → Exporting a reversal script ahead of time.
These exports are vendor-aware:
- SQL Server produces a single
.sqlfile with batches separated byGO. - Oracle lets you choose, in the save dialog's Save as type, between a single
.sqlfile (PL/SQL blocks terminated with/) and a.zippackage. The package holds each script plus adeploy.sqlyou can run in SQL*Plus (@deploy.sql) and amanifest.mffor re-running through DataStar. The.zipis the more robust Oracle choice (it carriesSET DEFINE OFFand runs each script separately) and is portable across Windows, macOS and Linux.
Either artifact can be re-run from Deployment → Run External Script.
Export Reversal Script pre-fills the save dialog with a descriptive name of the form {kind}_{task}_{database}_{timestamp}.{ext} - for example reversal_PROJ-123_DEV-SQL_20260628153012.sql. The task segment is included only when the deployment is attached to a task, and the timestamp is yyyyMMddHHmmss.
Pinned and Branch mode
A deployment file is in one of two modes, shown on the toolbar as Pinned or Branch:
| Mode | What is deployed |
|---|---|
| Pinned | Each item as it was at the commit it is pinned to (the Version column). Items can be updated or held back one at a time. This is how deployment files have always worked. |
| Branch | Every item as it is on the branch at one commit: HEAD when you deploy from the client, the build revision when build packages it in a pipeline. Items cannot be held back at an older commit one at a time. |
New files start in the mode the workspace's Deployment Mode setting names (workspace settings); the default is Pinned. Clicking the mode on the toolbar offers Switch to Branch or Switch to Pinned, unless the workspace has Allow Switching Deployment Mode turned off. A file already in the other mode still opens and deploys in its own mode either way.
- Switching to Branch moves every item to
HEADnow, and from then on the items follow it. The confirmation warns:Items pinned to older commits lose those pins. Switching back pins each item to its latest commit, not to the commit it was pinned at before.IfHEADcannot be read from version control, the switch is undone and explained; the file stays in Pinned mode. - Switching to Pinned pins every item to the latest commit that changed it. If any item has no commit to pin to (version control could not be read, or the file was never committed), the switch is refused with a message naming those items, and the file stays in Branch mode.
In Branch mode the items follow HEAD, so there is no older commit for them to be left at. Opening a Branch-mode file stamps every item with the commit HEAD is at, without asking and without marking the file as changed. An item that is not in the branch at that commit is flagged Not in the branch at <commit>.
Because every item is at one commit, that commit is shown once, in a header above the grid, rather than on every row: BRANCH MODE and the branch, the commit (the changeset on TFVC) and its message, who made it and when, and a Follows HEAD chip. Hover over the chip for Every item follows HEAD: deploying from here takes the commit HEAD is at when you deploy.
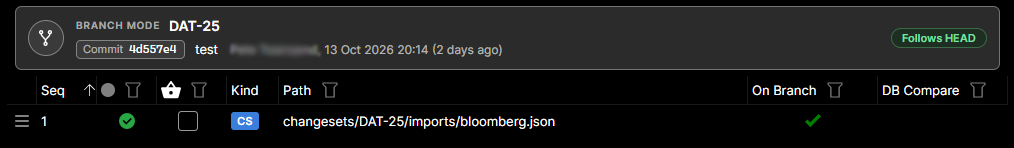
A line above the grid still appears when the file is not in the workspace's mode (This deployment is in Branch mode, but the workspace deploys in Pinned mode: ..., with the switch offered beside it).
Deploy, What If, Database Snapshot, SQL Export and Export Reversal Script read HEAD again first (Reading HEAD...) and stamp the items with it, so what they produce is what the branch holds when you run them. If HEAD cannot be read they are refused (A Branch-mode deployment is taken from the commit HEAD is at, and HEAD could not be read from version control. Check the connection to version control and try again.) rather than run at the commit the items last carried. Saving a Branch-mode file warns (Uncommitted Changes) when a listed file has changes that are not committed, since HEAD, and so the deployment, does not hold them.
The per-item version columns (Version, its date, Latest Version and Is Latest) are taken out in Branch mode, where the header shows the one commit every item carries, and Update to Latest and Compare with Latest are not offered. Opening a Pinned-mode file whose items were repaired while their versions were checked marks the file as changed, so you can save or discard the change rather than lose it when the tab closes.
File format
The workspace's Deployment File Format setting chooses whether a new file, or one saved fresh to a task, is written as deployment.xml or deployment.json. A file that is opened is saved back in its own format; Save As with the other extension converts it. build and the client read either.
The two formats store a Branch-mode file differently:
-
JSON names no commit on its items. The file says
"mode": "Branch", and each item has itspath(and baseline, variables and so on) but noversionorcheckinDateTime. A file committed to the repository can never name the commit that contains it, so a commit in a Branch-mode file could only ever be an earlierHEAD. A Branch-mode JSON file saved by an earlier version, with commits on its items, still opens; the commits are ignored. A Pinned-mode JSON file still needs aversionon every item, and one without is refused with'<path>' in the deployment file has no version. A Pinned-mode file pins every item to a commit; only a Branch-mode file leaves the commit out. -
XML keeps a
Versionon every item, the commitHEADwas at when the file was saved, because the schema requires it and older readers (DataStar 3.0 and Octopus steps) deploy it. The file says so in a comment at the top, after theGeneratedline:<!-- Branch mode: items are built from HEAD (or the build revision). Item Version is the commit at the last save, kept only for older readers. -->Each save stamps the items with
HEADagain and writes the comment afresh.
JSON suits Branch mode best. Pinned-mode files, and Branch-mode XML files, are unchanged for every reader.
A Branch-mode JSON file saved by DataStar 3.1.4 or later has no version on its items, and DataStar and DataStar.Tools 3.1.0 to 3.1.2 refuse it with '<path>' in the deployment file has no version. Upgrade every client and every pipeline that reads such a file, including the DataStar.Tools version a pipeline installs, or keep Branch-mode files in XML until they are upgraded.
Reading the deployment grid
Each row pins an item to a specific commit (the Version column). A few columns and indicators make it obvious when reality has moved on:
- Latest Version. The newest commit where the file still exists. For a file that's been deleted upstream this is the last commit before the delete, not
HEAD, so Update to Latest never tries to update to a version that doesn't contain the file. Pinned mode only. - Is Latest. Only ticked when the pinned version matches the latest version that contains the file. Pinned mode only.
- Kind. What the row is:
CSa changeset,SSa data document deployed whole (a snapshot),TRa script a template triggered. Blank for a plain script. Hover for the words behind the letters. - Deleted-upstream rows are highlighted with a delete icon in the status column, and a banner at the top of the view tells you how many items are affected.
Per-row preview
Right-click any row in the deployment grid and open Compare With… to compare the item, at the version it carries, with:
- Compare with Latest. The newest version of the file. Pinned mode only.
- Compare with Workspace. The file in your workspace, which you can edit in the diff.
- Compare with Current Connection. The database you're connected to, as it is now.
- Compare with Database... A database you pick, as it is now. Like Database Snapshot for one row, and it leaves the grid's snapshot statuses alone.
- Compare with DB Snapshot. The database as the last Database Snapshot found it. Available once you've run one, for rows it could compare.
- Compare with Branch... The file on a branch you pick (Git).
- Compare with Remote. The file on the remote branch that the checked-out branch tracks, fetched first (Git).
What a compare with a database shows depends on the item:
- A data document compares as JSON: the document at its version beside the component captured from the database as an extract would write it, so you read rows, not generated SQL. A component the database doesn't hold reads as
(not in <database>). If the component can't be captured, the row falls back to comparing the SQL the document deploys as. - A changeset compares as its changeset file beside the same changes as the database holds them now, both in the changeset file's JSON, with the counts in the title.
- A script compares with the database's own script of that object.
The rest of the menu:
- View History. Lists only the commits that actually changed this file. Merge commits that simply brought a branch forward are filtered out so they don't clutter the history with misleading "Modified" entries. The same rule applies wherever items get added to a deployment, including Add From Basket and the Release Workflow wizard.
- Open Script. Opens the pinned version (not the working copy). The tab title shows the version, e.g.
myscript.sql @1abb94c, and the file is read-only, but it isn't locked while you're reading it. Works the same on Git and TFVC. For a data document or a changeset this is the SQL it inflates to. - Open Document (JSON). For a data document or a changeset, the rows the item carries at the version it carries, read-only; for anything else, the file itself.
Deployment history
Deployments that ran successfully appear in Deployment → History; see the history tab for the audit log, including links back to re-run or reverse a previous deployment.
What's next
- The Release Workflow: a guided wizard that produces and runs a deployment in one flow.
- Deployment history: audit trail and reversal.